
Artificial Analysis gives Meta’s Muse Ember a score of 36 at $0.14 per index task, while finding low factual accuracy and frequent refusals.
The Latest
Meta’s Muse Ember Scores 36 At $0.14 Per Task—But Often Says “I Don’t Know”

Claude Fable 5.2 Is The New #1 AI Model. What Each Effort Level Costs You Per Task

Artificial Analysis ranks Claude Fable 5.2 first at Max effort, but its task cost rises from $3.10 at Low to $26.54 at Max.
14 Best Veterans Appreciation Gifts for Meaningful Thank-Yous in 2027
Compare 14 veterans appreciation gifts, from keepsakes and cards to drinkware and group sets, to find a thoughtful fit for your recipient and occasion.
15 Best American Flags for Outdoor Displays in 2027
Compare 15 American flags for outdoor displays by fabric, size, stitching, and mounting hardware to find a fit for your flagpole and weather.
Apple Blocked Swipe-typing For 100,000 Words And Phrases. Among Them Are ‘Dictator Trump’ And, In Russian, Phrases About Putin And Deploying Troops.
Researcher Derik Kauffman found an iOS list that blocks about 100,000 words and phrases from swipe typing and predictive suggestions.
How 80% Ended Up In Services

A history of U.S. employment shares traces service-sector growth to productivity differences, rising wages and the limits of automating labor-intensive work.
How T3 Code Brings Claude Code And Codex Subscriptions Into One Workspace

The free, open-source T3 Code app brings multiple coding agents into one interface while users keep their existing provider subscriptions.
How AI Agents Remember: What Anthropic’s Memory Research Shows, And What We Learned Running Agents With Memory
Anthropic’s November 6 research post describes how Claude agents save, organize and correct memories between sessions, with results from company-run tests.
The Rise And Retreat Of Factory Work
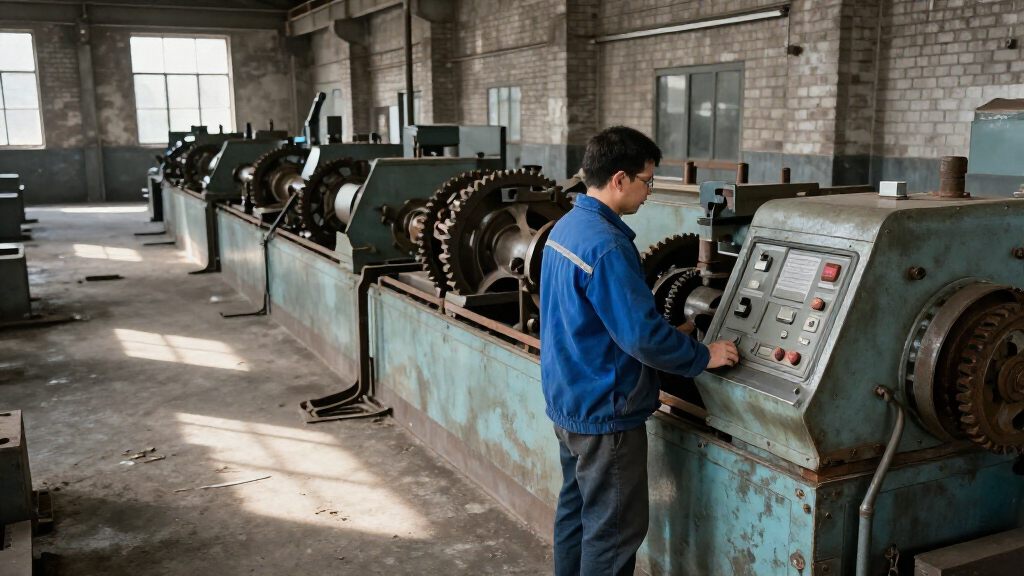
U.S. manufacturing employment fell to a preliminary 12.7 million in October 2026, while factory output remained nearly twice its 1979 level.
Terminal-RSI, Checked: Did An AI Agent Really Improve Itself With No Humans Involved?
Terminal-RSI reports benchmark gains from a human-designed training pipeline. The paper does not show an AI improving itself without human involvement.